


Financial Data Aggregation in Open Banking: A Practical Guide for Fintechs

September 18, 2026
- Financial data aggregation is infrastructure. The provider you choose determines your data quality, fallback behavior under outages, and your Section 1033 compliance posture for the next several years.
- The global financial aggregators market reached $6.9 billion in 2025 and is projected to grow at 15.5% CAGR through 2033.
- In the US, Section 1033 is enjoined and under active reconsideration, but the underlying market shift to permissioned, API-based data sharing is irreversible regardless of the rule's final form.
- Plaid, MX, Finicity, Yodlee, and Akoya differ sharply on connection method, OAuth coverage, data quality, and pricing.
Your lender’s credit decisioning model breaks because the transaction history it ingested was 48 hours stale. Imagine a situation: your PFM app’s account balance widget shows data from last Thursday, a user resets their bank password, and your aggregation link fails with no error, no alert, just a blank dashboard.
These are the production realities of aggregation built on the wrong architecture or the wrong vendor. The stakes for fintech CTOs and product leaders across fintech app development have never been higher. The aggregator you choose today shapes your compliance exposure, your data quality, and your unit economics for the next three to five years.
This guide covers what data aggregation is, how open banking API integration works step by step, how the five dominant providers compare, and what your compliance checklist needs to include before you go live.
What Is Financial Data Aggregation?
It’s the process of collecting, normalizing, and presenting account data from multiple financial institutions into a single, unified view. A financial aggregator connects to banks, credit unions, investment platforms, and card issuers on the user’s behalf, pulling balances, transactions, and account identity data from multiple accounts into one data exchange.
In practice, account aggregation powers personal financial management apps, credit decisioning engines, income verification tools, wealth management platforms, and open banking-powered payment flows. It is also the data foundation for any neobank built on API-based data connections. For a deeper look at how this fits into a broader product stack, see our overview of open banking infrastructure.
Financial data aggregators do three things:
- Establish authenticated connections to financial institutions through APIs or, where APIs are unavailable, screen scraping as a fallback.
- Normalize the raw data from dozens of different source formats into a consistent schema your application can consume.
- Maintain those connections over time, handling token refresh cycles, consent re-authorization, and institution-side changes.
The distinction between aggregator types matters. A financial data aggregation API like Plaid or MX is a commercial abstraction layer. This is one integration that covers thousands of institutions. A bank-owned network like Akoya is a different architecture entirely: institution-controlled, credential-free, and aligned with where regulatory pressure is heading. Understanding which model fits your product is the first decision, not the last.
Why This Market Is Accelerating Now
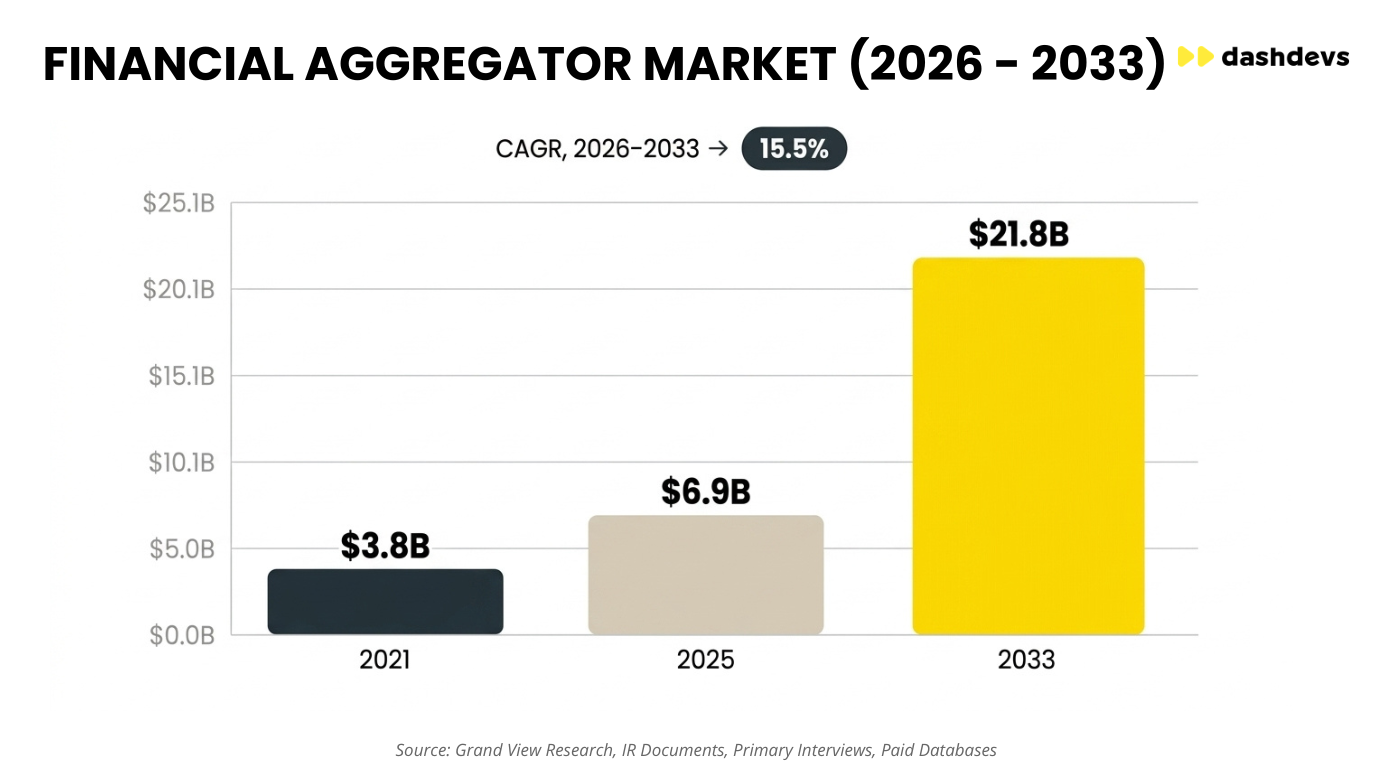
The market reached $6.9 billion in 2025 and is projected to reach $21.9 billion by 2033 at a 15.5% CAGR. North America holds the largest regional share at 39.5% of 2025 revenue, driven by the concentration of Plaid, MX, Finicity, and Yodlee in the US market.
Three structural forces explain the acceleration.
Regulatory mandates are forcing open APIs. PSD2 mandated API-based data sharing across the EU. Australia’s Consumer Data Right extended the same model to banking. In the US, the CFPB’s Section 1033 rule established the right for consumers to share their financial data with authorized third parties electronically. Even with the rule currently enjoined and under reconsideration, every major institution is building for the API-first future it signals. The direction is not in dispute; only the timeline is. For context on how PSD2 open banking regulations shaped the EU model that US regulators are referencing, that history matters.
Screen scraping is becoming unviable. Banks are actively blocking credential-based scraping through CAPTCHAs, rate limiting, and IP restrictions. When a consumer resets their credentials or a bank updates its digital interface, screen-scraped connections break silently. Akoya reports that up to 53% of a bank’s online traffic can come from bots and screen-scraping activity. That figure makes blocking economically and operationally necessary for any institution managing server load and security risk simultaneously.
Demand for real-time financial insight is non-negotiable. Embedded finance, instant lending, and AI-driven financial planning all require clean, fresh, structured data from multiple accounts. A 48-hour-old transaction snapshot cannot underwrite a BNPL decision. An API-based aggregator with sub-second latency can. The same data infrastructure that powers PFM apps is now the backbone of banking-as-a-service companies offering embedded financial products across non-banking verticals.
The market isn’t waiting for regulation to catch up. The commercial and technical shift from credential-based scraping to permissioned API access is already underway.
How Open Banking API Integration Works
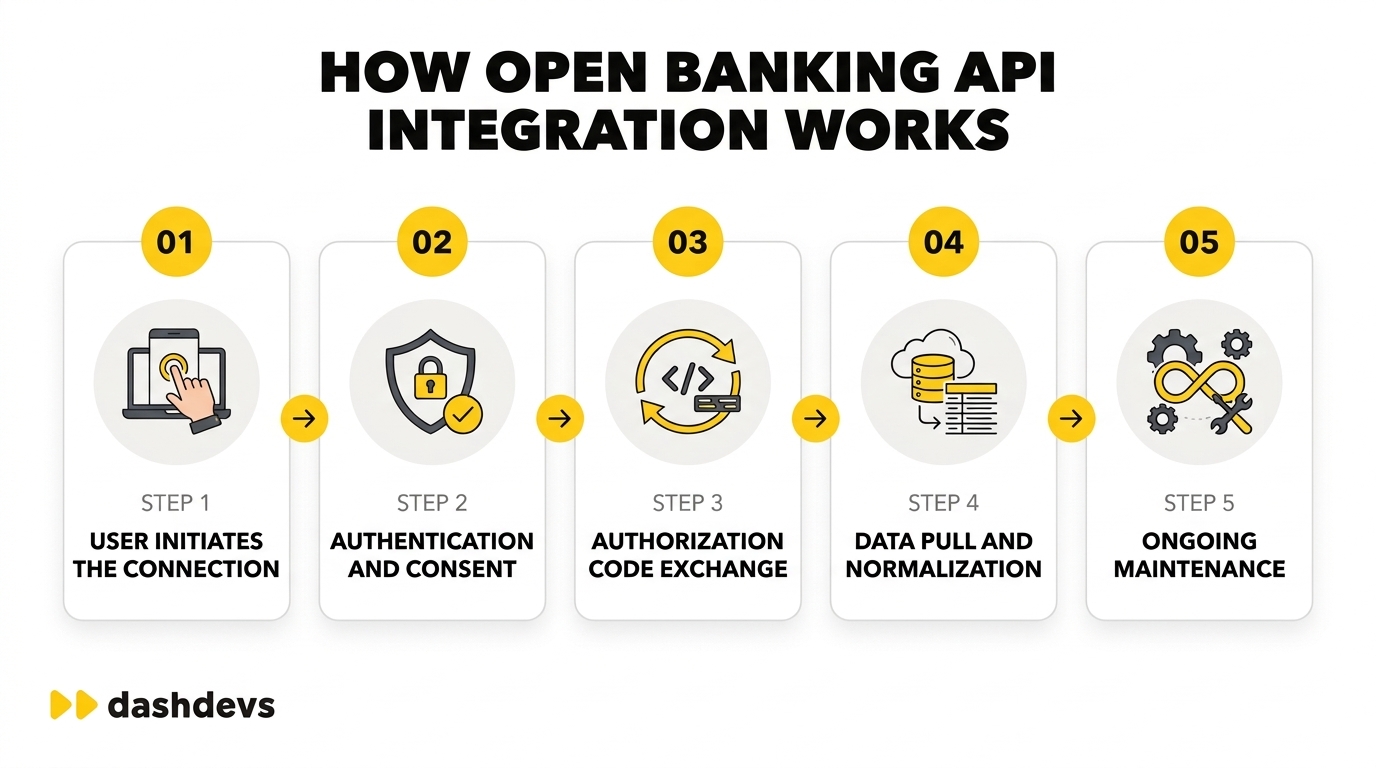
The OAuth 2.0 authorization code flow is the foundation of every compliant open banking integration. Here is exactly how the handshake works in production. For a broader look at open banking API mechanics, we have a separate guide covering bank API architecture in full.
Step 1: User Initiates the Connection
The user selects their bank inside your application. Your app redirects them to the aggregator’s consent interface (Plaid Link, MX Connect, or a similar UI component), which handles bank selection and branding.
Step 2: Authentication and Consent
The aggregator redirects the user to their bank’s own authentication endpoint. The user logs in through the bank’s interface and explicitly approves the scope of data access: account balances, transaction history, and identity data. This is the critical difference from screen scraping. The user’s credentials never leave the bank.
Step 3: Authorization Code Exchange
After successful authentication, the bank generates a short-lived authorization code and passes it back to the aggregator via a redirect URI. The aggregator exchanges that code for an access token and a refresh token at the bank’s token endpoint.
Access tokens are typically valid for 24 hours. Refresh tokens allow re-authentication without user action, subject to the consent duration the user approved.
Step 4: Data Pull and Normalization
With a valid access token, the aggregator calls the bank’s account and transaction endpoints. Raw responses (different schemas, currencies, date formats, and merchant names) are normalized into your agreed data model before delivery to your application.
Step 5: Ongoing Maintenance
The aggregator handles token rotation, reconnection flows when consent expires, and fallback behavior when the primary bank API is unavailable. Your application receives a consistent data feed regardless of what happens upstream.
The hard part is building the error-handling logic, reconnection flows, and monitoring stack that keeps the feed reliable in production when banks change their API schemas without notice.
A note on PKCE. For mobile and single-page applications, the standard OAuth flow is vulnerable to authorization code interception. Proof Key for Code Exchange (PKCE), now standard across all serious aggregators, closes this gap by adding a cryptographic challenge to the code exchange. It is not optional for production builds serving mobile users.
Comparing the Five Leading Data Aggregators
No single aggregator is the correct default. The decision turns on your institution coverage requirements, your use case (lending vs. PFM vs. payment initiation), your OAuth-to-scraping ratio tolerance, and your budget model. Below is a direct comparison of the five account aggregation providers relevant to a US fintech in 2026.
| Provider | Connection Method | Institution Coverage | Best For | Pricing Model |
|---|---|---|---|---|
| Plaid | API + OAuth + fallback scraping | 10,000+ institutions | Broad consumer connectivity, fast launch | Per successful link (~$0.30–$1+) |
| MX | API + OAuth + fallback scraping | 16,000+ data sources | Data enrichment, transaction categorization | Subscription + usage fees (~$5K+/month) |
| Finicity (Mastercard) | API + OAuth + direct agreements | 15,000+ institutions | Income/asset verification, lending | No public pricing; free sandbox |
| Yodlee (now STG) | API + OAuth + legacy scraping | 17,000+ data sources | Enterprise breadth, investment accounts | Subscription ($5K–$50K+/month) |
| Akoya | 100% API — no scraping | 4,300+ FIs (direct API only) | Credential-free architecture, Section 1033 readiness | No public pricing |
How to Read This Table
Plaid, one of the leading open banking players, remains the default for teams that need the fastest path to production and broad consumer bank coverage. A February 2026 benchmark by Phoenix Strategy Group recorded median API latency of 380 ms for Plaid, 420 ms for MX, and above 500 ms for Finicity. Its pricing model works well at the early stage but compounds significantly at scale.
MX leads on data quality. Its transaction categorization accuracy and enrichment taxonomy are the strongest of the three traditional aggregators, making it the right choice when clean inputs to a credit model or financial planning engine matter more than raw speed to market. Its support rating on G2 (9.4/10) is the highest of any aggregator, worth factoring in for teams without a large internal ops function.
Finicity (now inside Mastercard) has accelerated its direct API agreements with JPMorgan Chase, Bank of America, Wells Fargo, and Capital One. That reduces scraping fallback for high-volume lending use cases. It is the preferred financial data aggregator for income and asset verification workflows aligned with Fannie Mae and Freddie Mac requirements.
Yodlee (now independently owned by private equity firm STG following Envestnet’s sale in September 2025) carries the broadest raw institution count but draws the lowest review scores on support and connection stability across independent benchmarks. It suits established enterprise teams with the integration resources to manage its complexity.
Akoya is structurally different from the others. It is a bank-owned network, jointly owned by Fidelity Investments, The Clearing House, and 11 member banks, including Bank of America, Capital One, Citi, and JPMorgan Chase. This provides 100% API-based connections with no credential sharing and no personal data stored by the aggregator. Its institution count is lower than the traditional players, but every connection is direct and stable. For teams building toward Section 1033 compliance, or for any use case where credential sharing is an unacceptable risk, Akoya is the architecture that matches the regulatory direction of travel.
The Build vs. Buy Decision
Building a proprietary financial data aggregation software stack is almost never the right answer for a fintech at a growth stage. Here is the production reality of in-house aggregation that vendor comparison tables do not show:
- Each bank has a different authentication flow, data schema, and rate limit policy. You are building thousands of integrations.
- Connections break constantly. Bank UI updates, MFA changes, and token expiry edge cases require a full-time team to maintain connection health at any meaningful scale.
- Normalization is a product in itself. Raw transaction data from different banks is inconsistent in merchant names, categories, currency handling, and date formats.
- Screen scraping at scale triggers bank bot-detection systems and creates legal exposure under terms of service that increasingly prohibit it.
The correct in-house build question is narrower: should you build the normalization and enrichment layer on top of a commercial aggregator’s raw feed, rather than the aggregator itself?
When to build on top:
- Your use case requires proprietary enrichment logic (custom categories, ML-based classification) that commercial aggregators don’t offer.
- You need to route connections across multiple aggregators by institution to maximize coverage and reliability.
- You are building in a market or vertical where no major commercial aggregator has coverage.
Build vs. Buy Checklist:
- Does the commercial aggregator cover 90%+ of your target institutions? → Buy.
- Do you need income verification aligned with GSE standards (Fannie, Freddie)? → Finicity first.
- Is credential-free architecture a hard requirement (enterprise clients, regulated use case)? → Akoya, even at lower coverage.
- Is transaction enrichment accuracy critical to your core model? → MX, potentially with a custom layer on top.
- Are you launching in a market where no major aggregator has coverage? → Evaluate regional providers or build selectively for that corridor.
If you are launching a financial product on top of aggregated data, the fintech app development layer and the account aggregation layer need to be designed together. Check out our article to know how to structure your modern fintech data architecture at this stage, which determines how expensive it is to change providers later.
Compliance: What You Need Before Go-Live
Financial data aggregation operates at the intersection of consumer data rights, banking regulation, and data privacy law. Getting this wrong is an operational and regulatory risk that compounds over time.
Section 1033 Status in 2026
The CFPB finalized its Section 1033 Personal Financial Data Rights rule. The rule required depository institutions with $250B+ in assets and large nondepository data providers to comply by April 1, 2026. That date arrived, but not as a binding enforcement trigger.
A federal court in the Eastern District of Kentucky issued a preliminary injunction barring CFPB enforcement. The CFPB then initiated reconsideration through an August 22, 2025, Advance Notice of Proposed Rulemaking, reopening four issues: who qualifies as an authorized third party, whether data providers can charge fees for data access, data security requirements, and data privacy obligations.
The rule is enjoined and under active reconsideration. The compliance dates remain on the books but are not being enforced.
What this means in practice for fintechs evaluating aggregators:
- The fee question is live. JPMorgan Chase already has bilateral agreements with major aggregators for data access fees. That cost will eventually flow into aggregator pricing. Factor it into your unit economics now.
- Section 1033’s core requirement (consumers can authorize third parties to access their financial data) represents the direction of the market regardless of the rule’s final form.
- Choosing an aggregator with a credential-free, API-first architecture (Akoya, Finicity’s direct connections) means your integration is already aligned with where the regulatory framework is heading.
For more on how open banking integration works across different regulatory environments, including EU vs. US frameworks, see our dedicated guide.
FCRA and CRA Considerations
If you are using aggregated financial data for credit decisions, employment screening, or tenant screening, you are operating in FCRA territory. Aggregators themselves are not consumer reporting agencies (CRAs), but if you are using their data in a decisioning workflow that affects credit, housing, or employment, you may be acting as one.
The practical implication: ensure your data use agreement with your aggregator explicitly governs permissible purposes, and document your adverse action notice processes before your first credit decision. This is not something to resolve post-launch.
Your Pre-Launch Compliance Checklist
- Consumer consent: You have a clear, specific consent flow that tells users exactly what data you are accessing, for how long, and why.
- Data minimization: You are only requesting the scopes you actually use. Requesting 24 months of transaction history when you need 90 days is a liability.
- Token and credential security: Access tokens are stored in an encrypted, isolated vault with strict access controls and audit logging.
- Breach notification: You have a documented incident response plan covering aggregator-side breaches that affect your users’ data.
- Data retention and deletion: You have defined retention periods and a user-initiated deletion workflow that covers data you hold, not just what the aggregator holds.
- FCRA alignment: If you use transaction or account data in credit decisioning, you have documented your CRA status determination with counsel.
Compliance is an ongoing operational posture. The aggregator you choose needs to support your audit trail, consent revocation flows, and data minimization controls.
How We Built MENA’s First Regulated Open Banking Platform
The compliance and architecture challenges of financial data aggregation are not theoretical for us. When Tarabut came to DashDevs, the goal was to build the first regulated open banking platform in the MENA region, under a $500K budget, with no prior regional open banking precedent to follow.
The core engineering challenge was not connectivity. It was regulatory alignment and integration breadth simultaneously. Bahrain’s Central Bank had issued new open banking legislation with no existing implementations to reference. Every architectural decision had to clear both technical and regulatory review.
DashDevs built the full open banking engine from scratch: real-time payment architecture, consent management, account aggregation across 24 commercial banks in Bahrain, and the AIS and PIS layers required for the CBB sandbox testing process. The team of 10 engineers delivered in 9 months.
The results: 8 commercial banks integrated in the first 6 months, 200,000+ app downloads, and a platform valuation that grew from £0 to £25M on the back of the initial launch. That scale of open banking infrastructure, built from zero, under a constrained budget and inside a brand-new regulatory framework, is the kind of project that clarifies what the hard problems actually are. See the full Tarabut case study.
The lesson that carries across every aggregation project we have touched since: the integration is not the risk. The risk is building the aggregation layer without understanding the consent lifecycle, the reconnection failure modes, and the regulatory perimeter of the market you are entering. If you are building on open banking-powered savings or investment products, the Chip case study is another relevant reference for how the data layer interacts with product behavior at scale.
For teams that want open banking integrations pre-built rather than assembled from scratch, our white-label fintech platform ships with those connections already in place.
Common Mistakes in Financial Data Aggregation Projects
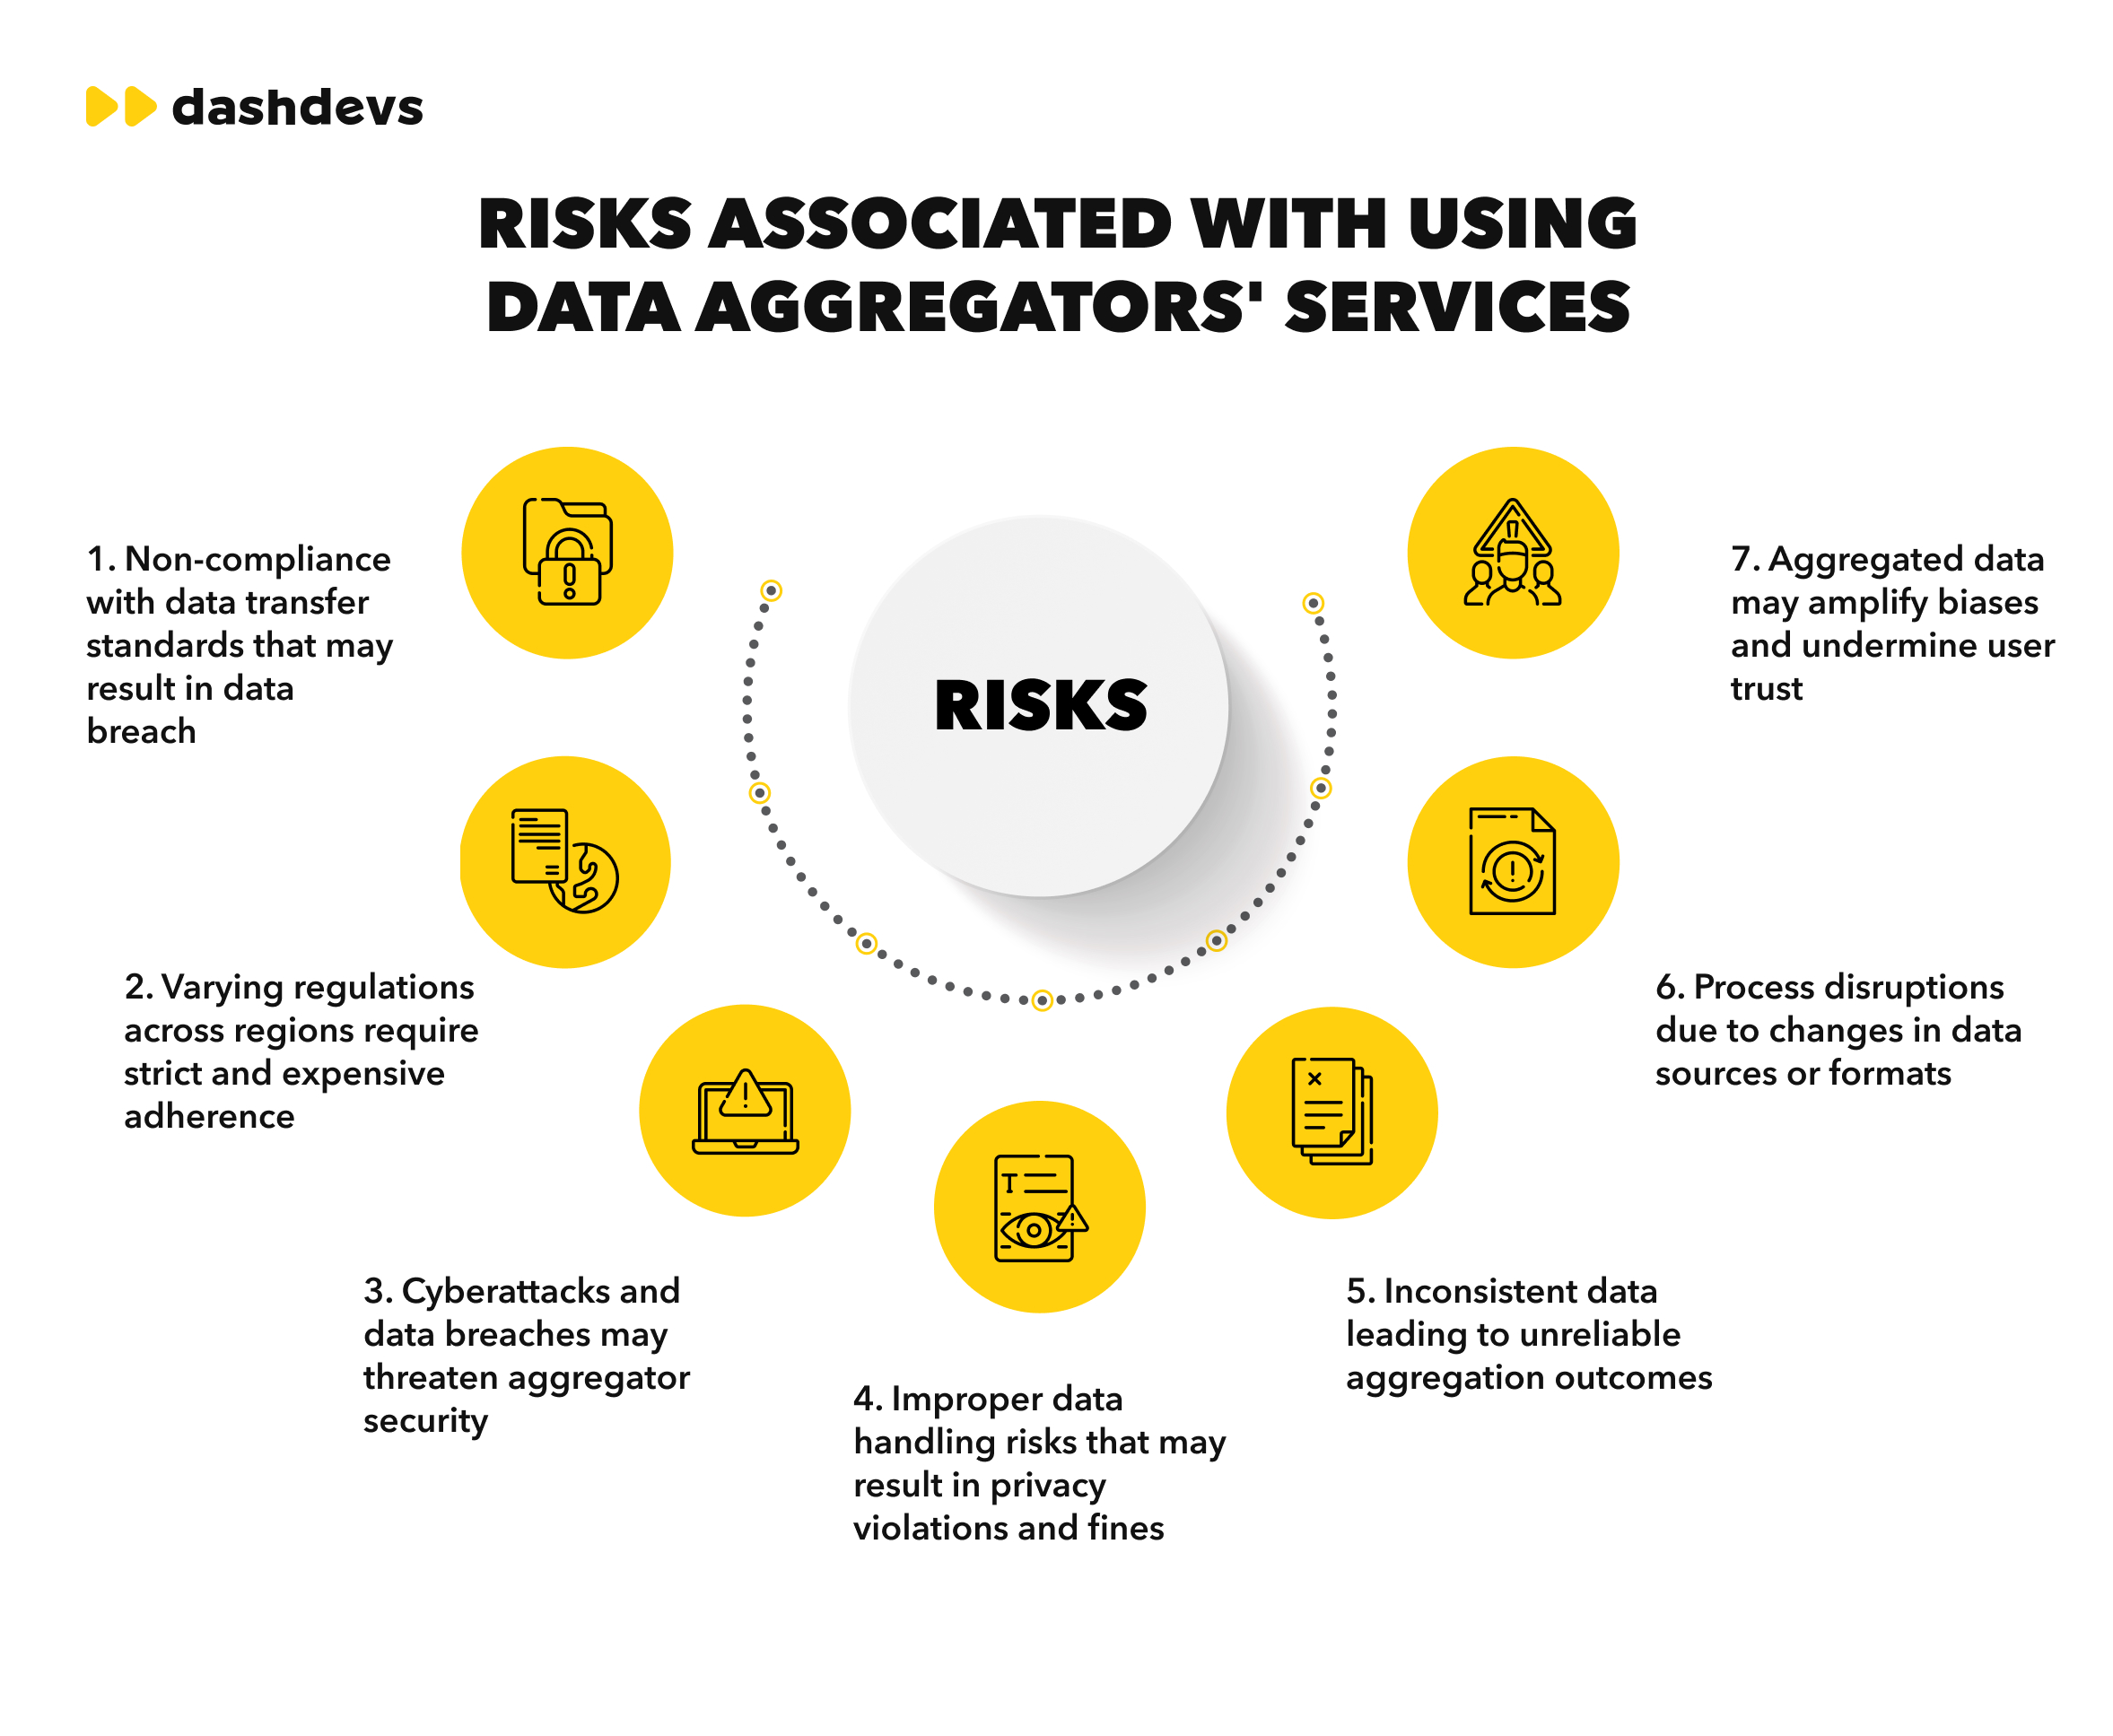
Choosing coverage count over connection quality. Yodlee’s 17,000+ data sources figure sounds definitive. In production, what matters is whether the specific institutions your users actually bank with have direct API connections or scraping fallbacks and how often those fallbacks fail. Test in a sandbox against your actual top 50 institutions before signing a contract.
Ignoring the fee question. JPMorgan Chase has already moved to charge aggregators for API access. That cost does not stay with the aggregator. Model what happens to your unit economics if per-connection costs increase 30% in 24 months.
Underestimating the consent UX. Reconnection flows (when tokens expire or users change passwords) are where most teams lose users. A clean aggregator SDK handles the happy path. The friction point is the re-consent experience. Own that design decision. Don’t outsource it entirely to the SDK.
Treat aggregator data as a source of truth. Transaction normalization is imperfect across all providers. Build validation and anomaly detection into your data pipeline. Don’t let raw aggregator output go directly into a credit model or balance calculation without a normalization layer you control.
Build for the current regulatory state, not the direction. The credential-sharing architecture that works today is the architecture regulators are systematically eliminating. Build toward OAuth-only flows and zero credential storage now, before a regulatory change forces a costly replatform.
The Regulatory and Market Shift Is Already Underway
The financial data aggregation market isn’t waiting for Section 1033 to be resolved. Major institutions are already building direct API infrastructure. Aggregators are already transitioning from scraping to OAuth. The fee structures that will define the next cycle of fintech unit economics are already being set in bilateral agreements between banks and aggregators.
The fintech teams that will have the structural advantage in three years are the ones that chose their aggregator for production reliability and regulatory alignment, not for the fastest demo or the lowest initial quote. That choice is happening now.
If you are evaluating an open banking API provider or selecting a financial data integration partner for your stack, the architecture decision you make in the next six months will still be live at your Series B.
Share article
